Blog
Is Your Website Not Showing Up in AI Search? Why JavaScript-Only Sites Are Invisible to ChatGPT, and the Fix
Why a JavaScript-only website is not showing up in AI search (ChatGPT, Claude, Perplexity): the view-source test, which crawlers render JS, and the SSR fix.
Quick Answer
If your website is not showing up in AI search, the most common technical cause is that it is built as a JavaScript application: the server sends an empty shell and a script, and the script draws the content afterwards. Google can run that script, slowly, in a second pass. The crawlers behind ChatGPT, Claude, Perplexity and most other AI assistants do not run it at all, so they receive a blank page. Research by Vercel and MERJ published in December 2024 found that none of the major AI crawlers rendered JavaScript, even though GPTBot downloaded script files in 11.5 per cent of its requests and Anthropic’s crawler in 23.8 per cent. The test takes ten seconds: view the page source and search for a sentence you can see on screen. The fix is to make the content, titles and structured data part of the HTML the server sends, through server-side rendering, static generation or a pre-rendering layer, and then to make sure Bing can index the result, because ChatGPT’s search draws heavily on Bing’s index.
A business owner in Dubai types “best marketing agency in Dubai for a clinic” into ChatGPT and gets a list of six names with reasons. Another asks Perplexity which web development companies in the UAE build bilingual sites, and gets four, with links. Neither of them opens Google. This is now a routine way buyers shortlist suppliers, and for a growing number of companies it produces a disturbing discovery: they rank on the first page of Google for exactly those terms, and the AI assistants have never heard of them.
The usual explanation reached for is “we need more content” or “we need to do GEO.” Sometimes that is true. But before spending a dirham on content, there is a technical check that explains a large share of these cases, and it has nothing to do with what your site says. It has to do with whether AI systems can read it at all. This article explains the problem in plain terms, shows you how to test your own site in under a minute, explains which crawlers can and cannot see JavaScript-rendered pages, describes why Bing matters more than most UAE businesses realise, and sets out the fixes, from a rebuild to a same-week patch that leaves your existing site untouched.
The Ten-Second Test
Open any important page on your website in a desktop browser. Do not open the developer inspector; that shows you the page after scripts have run, which is exactly what you must not look at. Instead, view the page source (in Chrome, right-click and choose “View page source”, or type view-source: before the URL). Now search that source, with Ctrl+F or Cmd+F, for a full sentence that you can see on the visible page: a line from your homepage introduction, a service description, a paragraph of a blog post.
If the sentence is there, your content is in the HTML and AI crawlers can read it. If it is not there, and instead you see a short document with a few <div> containers, script tags, and perhaps template placeholders such as {{ title }} or a <div id="root"></div>, then your content is being generated in the browser after the page loads. To a crawler that does not execute scripts, your page is that short document and nothing else.
Do the same test for the page title. If every page in the source shows the same <title> and the real titles only appear once the page has loaded, the crawler is indexing one title for your whole site. You can run the same check from a terminal with curl against the URL, which is what a crawler actually receives. If you disable JavaScript in your browser and reload the page, you will see with your own eyes what those crawlers see.
If you want to know how we came to write this article, the answer is that we ran this test on our own website while planning it, and it failed. More on that below.
Which AI Crawlers Render JavaScript and Which Do Not
The most rigorous public data on this comes from Vercel, a hosting platform, working with the technical SEO consultancy MERJ. In “The rise of the AI crawler”, published in December 2024, they analysed crawler traffic across Vercel’s network and reported that Googlebot made about 4.5 billion fetches a month, GPTBot about 569 million, Anthropic’s Claude crawler about 370 million, Apple’s crawler about 314 million and PerplexityBot about 24.4 million. Their headline finding on rendering was unambiguous: none of the major AI crawlers rendered JavaScript. That included OpenAI’s three crawlers (OAI-SearchBot, ChatGPT-User and GPTBot), Anthropic’s ClaudeBot, Meta’s ExternalAgent, ByteDance’s Bytespider and PerplexityBot. The two exceptions were Google’s own crawler, which uses Google’s Web Rendering Service and therefore also feeds Gemini, and Apple’s crawler.
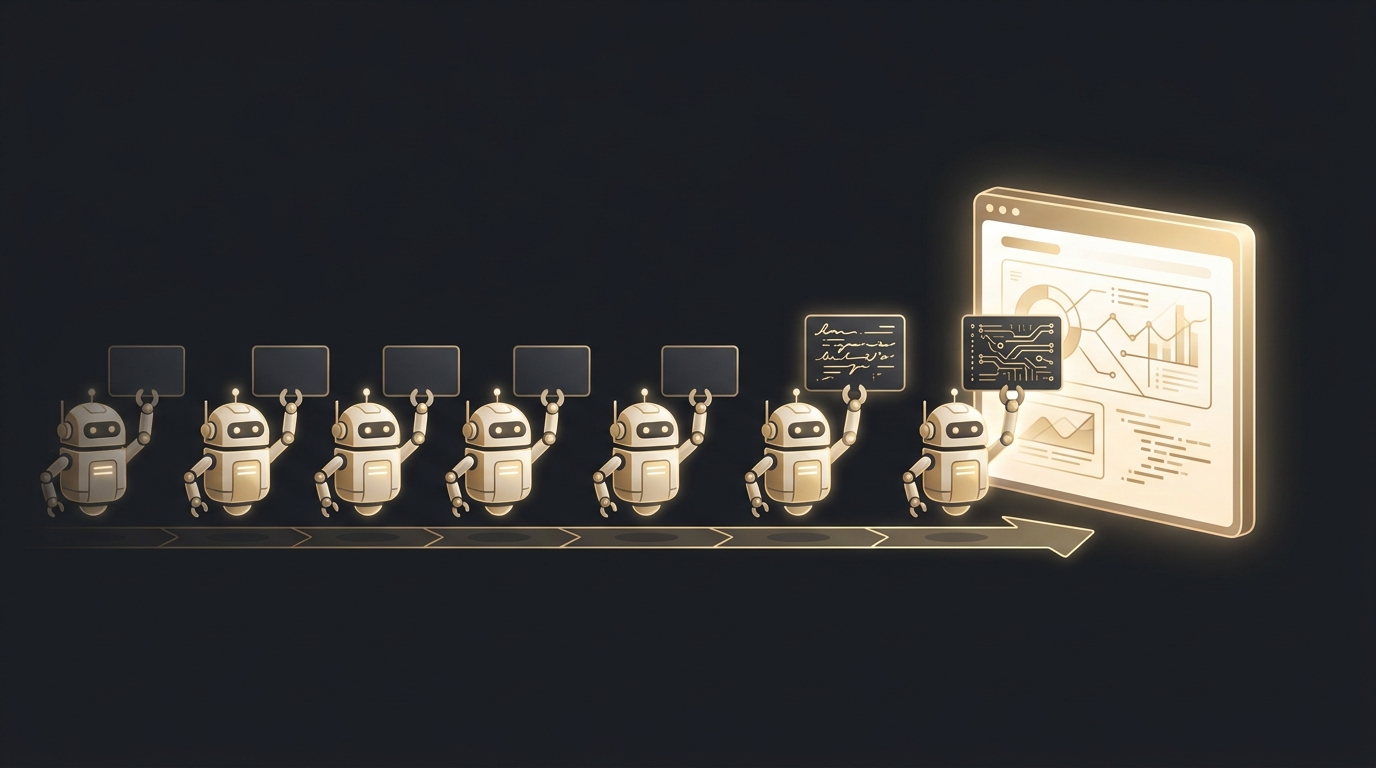
The detail that matters for anyone tempted to assume “they will get there” is what the crawlers did with script files. GPTBot fetched JavaScript files in 11.5 per cent of its requests and Claude’s crawler in 23.8 per cent. They downloaded the scripts and did not execute them. As Vercel put it, they cannot read client-side rendered content. Downloading a script is not the same as running it, and a page whose content depends on the script running remains empty to them.
| Crawler | Operator | What it feeds | Renders JavaScript? |
|---|---|---|---|
| Googlebot | Google Search, AI Overviews, Gemini | Yesvia Web Rendering Service, in a second pass | |
| Applebot | Apple | Siri and Apple search features | Yes |
| GPTBot | OpenAI | Model training | No |
| OAI-SearchBot | OpenAI | ChatGPT search index and citations | No |
| ChatGPT-User | OpenAI | Live fetches when a user asks about a page | No |
| ClaudeBot | Anthropic | Claude | No |
| PerplexityBot | Perplexity | Perplexity answers | No |
| Meta-ExternalAgent | Meta | Meta AI | No |
| Bytespider | ByteDance | ByteDance AI products | No |
Source: Vercel and MERJ, The rise of the AI crawler, December 2024; OpenAI crawler documentation.
Two nuances are worth stating so the article is not misread. First, “renders JavaScript” and “shows your site in answers” are different things; rendering is a prerequisite, not a guarantee. Second, this was a December 2024 snapshot, and crawler capabilities change. We have seen no public evidence since then that OpenAI, Anthropic or Perplexity have begun executing JavaScript at crawl time, and their own documentation does not claim it. Until they do, the safe engineering assumption is that they do not.
Why ChatGPT Depends on Bing More Than on Google
There is a second layer to AI visibility that UAE businesses almost never address: which search index the assistant leans on when it goes looking. For ChatGPT, the answer is largely Bing. Seer Interactive analysed more than 500 citations from ChatGPT’s search feature in February 2025 and found that 87 per cent of them matched Bing’s top organic results, against only 56 per cent that matched Google’s. ChatGPT’s search product was built on a partnership with Microsoft, and its live retrieval reflects that.
The implication is uncomfortable for a market that has spent a decade optimising exclusively for Google. A UAE business that has never verified its site in Bing Webmaster Tools, never submitted a sitemap to Bing and never checked how Bing indexes its pages has left the door half closed on ChatGPT specifically. Bing also has its own, more limited, approach to JavaScript rendering, which makes the server-rendered HTML fix doubly important. The good news is that the work is small: verify the site in Bing Webmaster Tools, submit the sitemap, and enable IndexNow so that new and updated pages are pushed to Bing immediately rather than waiting to be discovered.
Client-Side, Server-Side and Pre-Rendering, Explained
The three approaches to building a modern website differ in one respect that matters here: where the content is assembled.
Client-side rendering sends the browser a nearly empty HTML file and a JavaScript application. The browser runs the application, which fetches data (from a content management system, a database, or a service such as Firebase) and builds the page. Frameworks such as React, Vue and Angular default to this when used without a server framework. It is fast to build, pleasant for developers, and invisible to any crawler that does not run scripts.
Server-side rendering (SSR) does the assembly on the server for every request, so the HTML that arrives already contains the content. Frameworks such as Next.js (for React) and Nuxt (for Vue) exist largely to make this straightforward. Static site generation (SSG) goes a step further and assembles every page in advance at build time, producing plain HTML files that any server can serve; incremental static regeneration refreshes individual pages when their content changes. Both approaches put the content, the title tags and the structured data into the initial HTML, which is exactly what crawlers need.
Pre-rendering is the middle path for sites that already exist as client-side applications. A pre-rendering service (Prerender.io is the best known) or a build step produces a static HTML snapshot of each page and serves that snapshot to crawlers, while human visitors still receive the JavaScript application. It can be added to an existing site in days rather than the weeks a rebuild takes. One caution: Google’s documentation now describes serving different content to crawlers and to users (“dynamic rendering”) as a workaround rather than a long-term solution, and recommends server-side rendering, static rendering or hydration instead. Pre-rendering is a legitimate bridge; treat it as a bridge.
| Approach | Where content is assembled | Visible to AI crawlers? | Effort on an existing site |
|---|---|---|---|
| Client-side rendering (SPA) | In the visitor’s browser | No | — |
| Pre-rendering layer | Snapshot generated for crawlers | Yes | Days |
| Server-side rendering | On the server per request | Yes | Weeks (framework migration) |
| Static site generation | At build time | Yes | Weeks (framework migration) |
What Must Be in the HTML
Rendering the body text is necessary but not sufficient. Four things should be present in the server-delivered HTML of every page. The <title> and meta description, unique per page, because a site that ships one title for every URL is telling every crawler that every page is the same. The headings and body content, in real HTML elements rather than injected later. Structured data in JSON-LD (schema.org Organization, LocalBusiness, Service, Article and FAQPage as appropriate), because AI systems use it to identify what a page is about and who is behind it. And the canonical URL, so that the address the crawler indexes is the one you want cited. If your site is served from a hosting platform’s default domain as well as your own, the canonical tag and the Open Graph URL should point at your domain, not the platform’s.
robots.txt: Which Bots to Allow
Many sites block AI crawlers without knowing it, because security plugins, CDN bot-management settings and copy-pasted robots.txt files from 2023 included blanket rules against “AI bots” when the concern was model training. If you want to be cited in AI answers, you need to allow the search-oriented crawlers at minimum. OpenAI documents three separate user agents, each controllable independently: GPTBot (used for training), OAI-SearchBot (used to index pages for ChatGPT search and citations) and ChatGPT-User (used when a user asks ChatGPT about a specific page). Blocking GPTBot while allowing OAI-SearchBot is a coherent position if you object to training use but want to appear in search; blocking all three is a decision to be invisible in ChatGPT. Anthropic’s ClaudeBot and Perplexity’s PerplexityBot follow the same robots.txt conventions, and Google-Extended controls whether your content is used for Gemini training without affecting Google Search. Check your live robots.txt file and your CDN’s bot rules, not the file in your repository; they are often different.
Fixing a React, Vue or Next.js Site Without a Full Rebuild
The right fix depends on what you have and how long you can wait.
If your site is on WordPress, Webflow, Shopify or a similar platform, you almost certainly do not have this problem; these platforms deliver server-rendered HTML by default. Run the ten-second test to confirm, then move on to content.
If your site is a Next.js or Nuxt application already, the fix is usually configuration rather than migration: switch the affected pages from client-side data fetching to server-side rendering or static generation, which these frameworks support natively. Titles and metadata move into the server-rendered head.
If your site is a plain React, Vue or Angular application (including sites that load their content from Firebase or a headless CMS at runtime), you have two paths. The fast path is a pre-rendering layer, which can be live within a week and immediately makes the content visible, accepting Google’s caution that it is a bridge. The durable path is migrating to a server-rendered framework, which is a project of weeks but removes the problem permanently and typically improves Core Web Vitals too. Many businesses do both: pre-render now, migrate over the next quarter.
Whichever path you take, the acceptance test is the same one you started with: view source, JavaScript disabled, and every important sentence, title and schema block is there.
How We Found This on Our Own Site
We ran the ten-second test on blackstoneservices.ae while planning this article, and it failed. Our site was built as a Vue application drawing its content from a cloud database at runtime. The page source contained template placeholders where the content should have been, and every URL carried the same title tag. It ranked; it was not readable by a single AI crawler. We are publishing that because it is the point of the article: this is not a problem that afflicts careless businesses. It afflicts modern, well-built sites whose builders optimised for the human experience and assumed the crawlers would keep up. The rebuild to server-rendered pages is described in our digital development work, and the acceptance test we used is the one above.
A Technical Checklist for AI Visibility
- View source with JavaScript disabled: body text, headings and a unique title present on every important page.
curlreturns the same content a browser shows, not an empty shell.- Structured data (Organization, Service, Article, FAQPage) present in the server-delivered HTML.
- Canonical and Open Graph URLs point at your own domain.
- robots.txt (the live one, and the CDN’s bot rules) allows OAI-SearchBot, ChatGPT-User, ClaudeBot, PerplexityBot and Googlebot; a considered decision made on GPTBot and Google-Extended.
- Site verified in Bing Webmaster Tools; sitemap submitted; IndexNow enabled.
- Site verified in Google Search Console; URL Inspection shows the rendered content.
- If pre-rendering is used, it is documented as a bridge with a migration date.
- Core Web Vitals within Google’s thresholds after the change.
- A monthly check: ask ChatGPT, Perplexity and Google AI Overviews the questions your buyers ask, and record whether you appear.
Being readable is the prerequisite. Being recommended is the next problem, and it depends on the content itself: sourced statistics, clear answers, structured comparisons and third-party mentions. Our upcoming guide on how UAE businesses get recommended by ChatGPT and other assistants covers that layer. If you would like us to run the ten-second test and the checklist against your site, start a project or read about our digital development services; a site that is invisible to AI is one of the first things we look for in a new engagement.
Frequently Asked Questions
Why does my website rank on Google but not appear in ChatGPT?
Most often because the site is built as a JavaScript application whose content is drawn in the browser after loading. Google executes JavaScript when it crawls; the crawlers behind ChatGPT, Claude and Perplexity do not, according to Vercel and MERJ’s December 2024 analysis, so they receive an empty page. A second factor is that ChatGPT’s search leans heavily on Bing’s index, and many sites have never been verified or indexed in Bing.
How do I check whether AI crawlers can read my website?
View the page source (not the inspector) and search for a sentence you can see on the page. If it is missing, the content is generated by scripts and is invisible to non-rendering crawlers. You can also disable JavaScript in your browser and reload, or fetch the URL with curl; what you see is what those crawlers see.
Does Google render JavaScript?
Yes. Googlebot fetches the page and then renders it with a headless browser in a second pass, so client-side content is usually indexed, though more slowly. Google’s crawler also serves Gemini. Google does not, however, recommend serving different content to crawlers and users as a long-term approach, preferring server-side rendering, static rendering or hydration.
What is the fastest fix for a JavaScript-only website?
A pre-rendering layer, which generates static HTML snapshots of each page for crawlers while visitors still get the application. It can be live within days. The durable fix is moving to server-side rendering or static generation with a framework such as Next.js or Nuxt, which takes weeks but resolves the problem permanently.
Should I block AI crawlers in robots.txt?
Only if you have decided you do not want to appear in AI answers. OpenAI publishes separate user agents: GPTBot for training, OAI-SearchBot for search indexing and ChatGPT-User for live page fetches. You can block training crawlers while allowing search crawlers. Check your live robots.txt and your CDN’s bot rules, because plugins and templates often block everything by default.
Run the ten-second test. Then let us fix what it finds.
If your content is missing from the page source, ChatGPT, Claude and Perplexity cannot cite you. We audit and fix AI visibility for existing sites without a full rebuild.
Get an AI Visibility Audit →